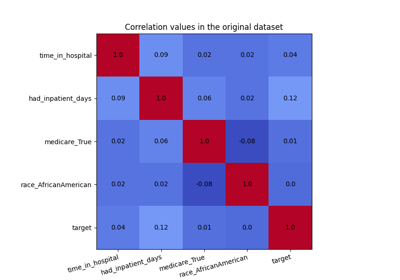
fairlearn.preprocessing.CorrelationRemover#
- class fairlearn.preprocessing.CorrelationRemover(*, sensitive_feature_ids=(), alpha=1)[source]#
A component that filters out sensitive correlations in a dataset.
CorrelationRemover applies a linear transformation to the non-sensitive feature columns in order to remove their correlation with the sensitive feature columns while retaining as much information as possible (as measured by the least-squares error).
Read more in the User Guide.
Added in version 0.6.0.
Changed in version 0.8.0: Added the
n_features_in_andfeature_names_in_attributes.Changed in version 0.12.0: The estimator became fully
scikit-learncompatible.- Parameters:
sensitive_feature_ids (
Iterable) – List of columns to filter out. This can be a sequence of either int, in the case of numpy, or string, in the case of pandas.alpha (
float) – Parameter to control how much to filter. For alpha=1.0 we filter out all information, while for alpha=0.0 we don’t apply any.
Notes
This method will change the original dataset by removing all correlation with sensitive values. In mathematical terms, assume we have the original dataset \(\mathbf{X}\), which contains a set of sensitive features denoted by \(\mathbf{S}\) and a set of non-sensitive features denoted by \(\mathbf{Z}\). The goal is to remove correlations between the sensitive features and the non-sensitive features.
Let \(m_s\) and \(m_{ns}\) denote the number of sensitive and non-sensitive features, respectively. Let \(\bar{\mathbf{s}}\) represent the mean of the sensitive features, i.e., \(\bar{\mathbf{s}} = [\bar{s}_1, \dots, \bar{s}_{m_s}]^\top\), where \(\bar{s}_j\) is the mean of the \(j\text{-th}\) sensitive feature.
For each non-sensitive feature \(\mathbf{z}_j\in\mathbb{R}^n\), where \(j=1,\dotsc,m_{ns}\), we compute an optimal weight vector \(\mathbf{w}_j^* \in \mathbb{R}^{m_s}\) that minimizes the following least squares objective:
\[\min _{\mathbf{w}} \| \mathbf{z}_j - (\mathbf{S}-\mathbf{1}_n\times\bar{\mathbf{s}}^\top) \mathbf{w} \|_2^2\]where \(\mathbf{1}_n\) is the all-one vector in \(\mathbb{R}^n\).
In other words, \(\mathbf{w}_j^*\) is the solution to a linear regression problem where we project \(\mathbf{z}_j\) onto the centered sensitive features. The weight matrix \(\mathbf{W}^* = (\mathbf{w}_1^*, \dots, \mathbf{w}_{m_{ns}}^*)\) is thus obtained by solving this regression for each non-sensitive feature.
Once we have the optimal weight matrix \(\mathbf{W}^*\), we compute the residual non-sensitive features \(\mathbf{Z}^*\) as follows:
\[\mathbf{Z}^* = \mathbf{Z} - (\mathbf{S}-\mathbf{1}_n\times\bar{\mathbf{s}}^\top) \mathbf{W}^*\]The columns in \(\mathbf{S}\) will be dropped from the dataset \(\mathbf{X}\), and \(\mathbf{Z}^*\) will replace the original non-sensitive features \(\mathbf{Z}\), but the hyper parameter \(\alpha\) does allow you to tweak the amount of filtering that gets applied:
\[\mathbf{X}_{\text{tfm}} = \alpha \mathbf{X}_{\text{filtered}} + (1-\alpha) \mathbf{X}_{\text{orig}}\]Note that the lack of correlation does not imply anything about statistical dependence. Therefore, we expect this to be most appropriate as a preprocessing step for (generalized) linear models.
- fit(X, y=None)[source]#
Learn the projection required to make the dataset uncorrelated with sensitive columns.
- Parameters:
X (array_like of shape (n_samples, n_features)) – The feature matrix. pandas DataFrame, Polars DataFrame, and PyArrow Table inputs are supported. Sensitive feature columns identified by
sensitive_feature_idsmust be present inX.y (Ignored) – Not used; present for API compatibility with scikit-learn.
- Returns:
self (object) – Fitted CorrelationRemover instance.
- Raises:
ValueError – If the number of features in
Xdiffers from the number seen during a previous call tofit.
- fit_transform(X, y=None, **fit_params)[source]#
Fit to data, then transform it.
Fits transformer to X and y with optional parameters fit_params and returns a transformed version of X.
- Parameters:
X (array_like of shape (n_samples, n_features)) – Input samples.
y (array_like of shape (n_samples,) or (n_samples, n_outputs), default=None) – Target values (None for unsupervised transformations).
**fit_params (
dict) – Additional fit parameters. Pass only if the estimator accepts additional params in its fit method.
- Returns:
X_new (
ndarrayarrayof shape (n_samples, n_features_new)) – Transformed array.
- get_feature_names_out(input_features=None)[source]#
Get output feature names for transformation.
The sensitive feature columns are dropped, so the output contains the non-sensitive features in their input order.
- Parameters:
input_features (array_like of
strorNone, default=None) – Input feature names. IfNone, the column names seen duringfitare used, or["x0", "x1", ...]ifXhad no column names. If given, it must match the column names seen duringfit.- Return type:
numpy.ndarrayofstr- Returns:
The names of the transformed features.
- Raises:
NotFittedError – If the estimator has not been fitted yet.
ValueError – If
input_featuresdoes not match the features seen duringfit.
- get_metadata_routing()[source]#
Get metadata routing of this object.
Please check User Guide on how the routing mechanism works.
- Returns:
routing (MetadataRequest) – A
MetadataRequestencapsulating routing information.
- set_output(*, transform=None)[source]#
Set output container.
Refer to the user guide for more details and Introducing the set_output API for an example on how to use the API.
- Parameters:
transform ({"default", "pandas", "polars"}, default=None) –
Configure output of transform and fit_transform.
”default”: Default output format of a transformer
”pandas”: DataFrame output
”polars”: Polars output
None: Transform configuration is unchanged
Added in version 1.4: “polars” option was added.
- Returns:
self (estimator instance) – Estimator instance.
- set_params(**params)[source]#
Set the parameters of this estimator.
The method works on simple estimators as well as on nested objects (such as
Pipeline). The latter have parameters of the form<component>__<parameter>so that it’s possible to update each component of a nested object.- Parameters:
**params (
dict) – Estimator parameters.- Returns:
self (estimator instance) – Estimator instance.
- transform(X)[source]#
Transform X by applying the correlation remover.
- Parameters:
X (array_like of shape (n_samples, n_features)) – The feature matrix to transform. pandas DataFrame, Polars DataFrame, and PyArrow Table inputs are supported. Must have the same number of features as the
Xpassed tofit.- Return type:
- Returns:
The transformed feature matrix with sensitive correlations removed. The sensitive feature columns are dropped; non-sensitive columns are replaced by their residuals after projecting out the sensitive features, blended with the originals according to
alpha.- Raises:
NotFittedError – If the estimator has not been fitted yet.
ValueError – If the number of features in
Xdiffers from the number seen duringfit, or named columns do not match the fitted column order.